Google's Transformer paper
“The 2017 Google paper 'Attention Is All You Need', which introduced the Transformer: the network design behind GPT, BERT and nearly every large language model since.”
'Attention Is All You Need' is the paper in which eight researchers at Google introduced the Transformer, a new design for the neural networks that work with language. It was sent to the NIPS conference on 19 May 2017 and posted openly on arXiv on 12 June. Its claim was in its title: a network built only from attention, a way for every word in a sentence to look directly at every other word, translated better than the best systems of the day and trained in a fraction of the time, three and a half days on one machine with eight Nvidia graphics processors. The Transformer is the T in GPT and in BERT, and nearly every large language model since, ChatGPT among them, is built on it.
Until then the best language systems were recurrent neural networks, above all the long short-term memory (LSTM) design of Sepp Hochreiter and Jürgen Schmidhuber (1997). They read a sentence one word at a time, passing a summary from step to step, so they were slow to train and lost track of words far apart. In 2014 Ilya Sutskever, Oriol Vinyals and Quoc Le at Google showed that such networks could translate whole sentences, and Dzmitry Bahdanau, Kyunghyun Cho and Yoshua Bengio added attention, letting the translator look back at the right words of the original; in September 2016 a system of this kind took over Google Translate's Chinese-to-English service. Jakob Uszkoreit, a Google researcher and the son of a computational linguist, argued that attention alone, with no recurrence at all, could do the job, and because it handles all the words at once it suits the parallel chips that were driving the deep-learning boom.
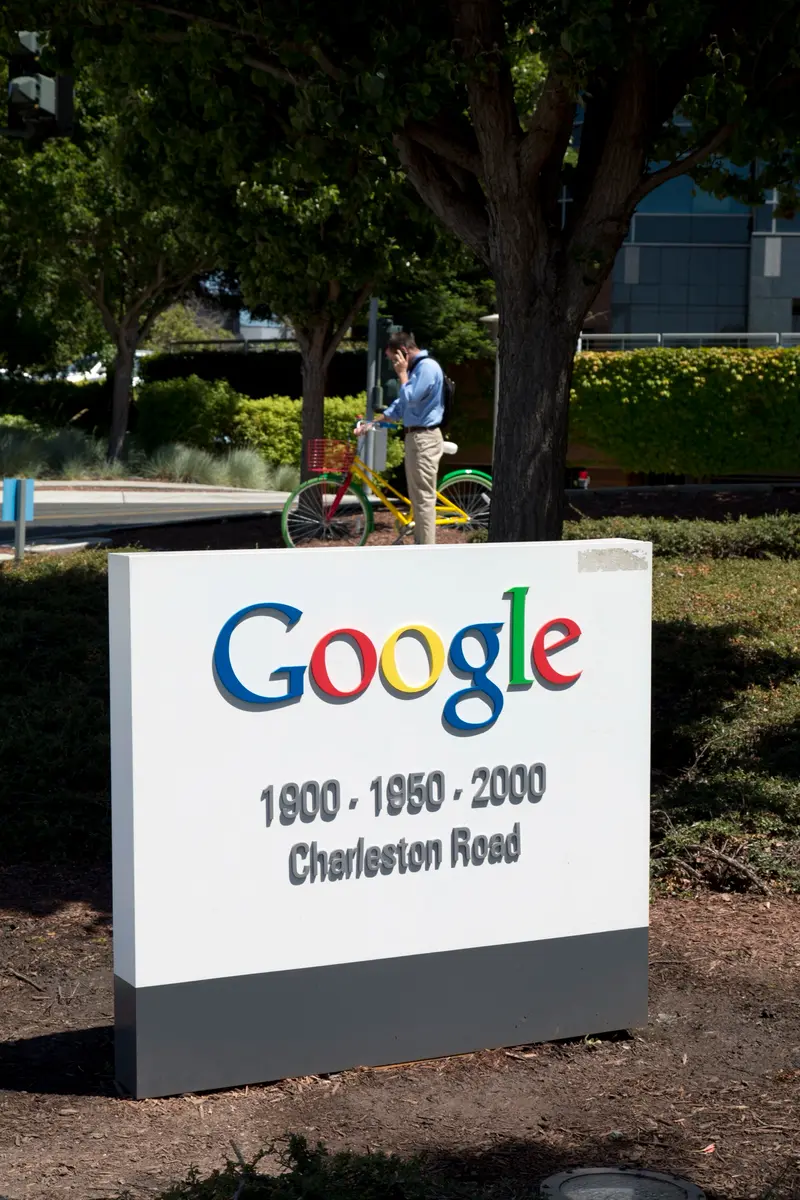
Uszkoreit, Illia Polosukhin and Ashish Vaswani began the project in 2016 in two neighbouring buildings on Charleston Road at Google's headquarters in Mountain View, California, and called it the Transformer from the start. Niki Parmar and Llion Jones joined them; Łukasz Kaiser and his intern Aidan Gomez, an undergraduate from the University of Toronto, brought their Tensor2Tensor code; and Noam Shazeer, at Google since 2000, rewrote the model and proposed the scaled dot-product attention, multi-head attention and position encoding that made it work. Jones took the title from the Beatles' 'All You Need Is Love', and the paper lists all eight as equal contributors in random order. Its big model scored 28.4 BLEU on the standard English-to-German test, more than two points above any earlier result. Google filed for a patent four days after the submission and released the code on 19 June, and the paper was shown as a poster at NIPS in Long Beach, California, on 6 December 2017.
Within a year the design escaped translation. In June 2018 OpenAI trained a Transformer on thousands of books to predict the next word and then adapted it to many tasks, the first GPT; in October 2018 Google's BERT, a Transformer that reads in both directions, set new records on eleven language tasks, and from October 2019 it helped rank one in ten English searches in the United States, a change Google called one of the biggest leaps in the history of Search. Scaled up with more data and computing power, the same architecture became the engine of the chatbots and image generators of the AI boom.
All eight authors have since left Google, most of them to found companies built on their invention: Gomez co-founded Cohere in Toronto in 2019, Shazeer Character.AI in 2021 (he returned to Google in 2024), Vaswani and Parmar Adept and then Essential AI, Jones Sakana AI in Tokyo, and Uszkoreit the biotech company Inceptive; Polosukhin, who had left before the paper came out, started what became the blockchain NEAR, and Kaiser joined OpenAI. Their story is often told as Google's missed chance: the company invented the technology, but a start-up, OpenAI, was first to turn it into ChatGPT.
What happened
- 2017
- 12:58 p.m.
Minutes before the deadline of 20:00 UTC (1 p.m. in Mountain View), the team submits 'Attention Is All You Need' to NIPS 2017, the year's main machine-learning conference; the last English-to-French result had come in only minutes earlier.
Google Building 1965, 1965 Charleston Road, Mountain View: Google Brain's building, where the team did most of the work in the weeks before the deadline Google files US provisional patent application 62/510,256 on the work, the first step to the patent 'Attention-based sequence transduction neural networks'.
Llion Jones posts the paper on arXiv, the open archive of research papers (17:57 UTC): the Transformer scores 28.4 BLEU on English-to-German translation, more than two points above every earlier result, after 3.5 days of training on eight GPUs.
Google releases Tensor2Tensor, an open-source library from Łukasz Kaiser's group that includes the Transformer, and version 2 of the paper points to it. Google's table puts the Transformer at 28.4 BLEU after 3 days on 8 GPUs, Google Translate's recurrent GNMT at 24.6 after 1 day on 96.
Jakob Uszkoreit presents the Transformer to the public on Google's Research Blog, with an animation of it translating and the example of 'it' in 'the animal didn't cross the street because it was too tired'.
- 6:30 p.m.
At NIPS 2017 in Long Beach the paper is shown in the Wednesday evening poster session, 18:30 to 22:30, in the Pacific Ballroom (poster 124). Version 5 on arXiv, posted the evening before, raises the English-to-French score to 41.8 and adds the footnote saying who did what.
Long Beach Convention Center: NIPS 2017, 4 to 9 December; the poster session of 6 December in its Pacific Ballroom - 2018
OpenAI shows that a Transformer pre-trained on a few thousand books simply to predict the next word, then fine-tuned, beats the best systems on many language tasks: the first GPT, from 'generative pre-training', trained for a month on eight GPUs.
Google researchers post BERT on arXiv, a Transformer pre-trained to fill in hidden words while reading in both directions, which sets new records on eleven language tasks; Google open-sources it on 2 November.
- 2019
The US Patent and Trademark Office grants Google patent 10,452,978, 'Attention-based sequence transduction neural networks', naming the paper's eight authors as inventors.
Google begins using BERT to rank results for about one in ten English-language searches in the United States, calling it one of the biggest leaps forward in the history of Search, and for the first time serves search results with its Cloud TPUs.